Google Cloud AI
By iAmaze
AI Powered extraction, classification & automation across any document type.
Extraction accuracy for standard documents
Reduction in manual data entry effort
Faster Document processing cycles
Languages supported by Vision OCR
Code needer for pre-trained processors
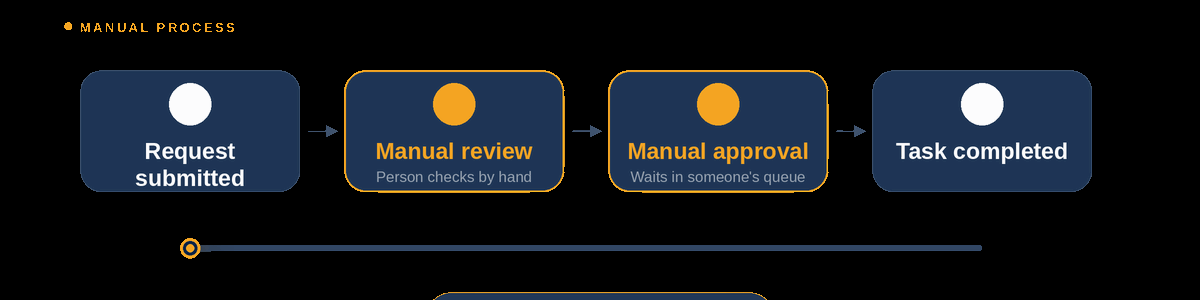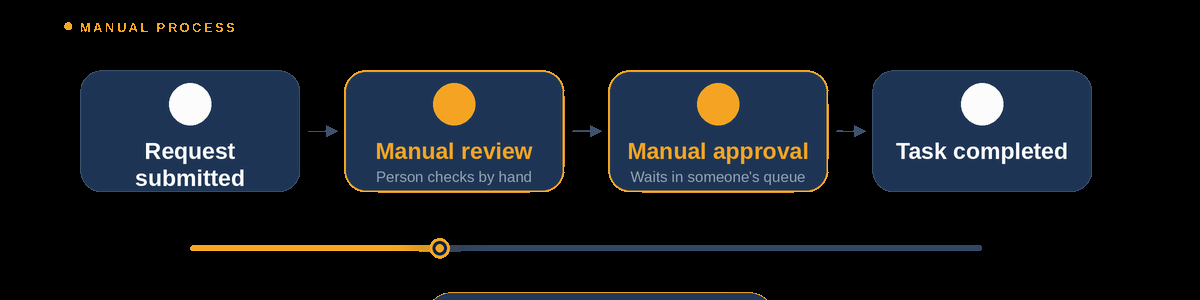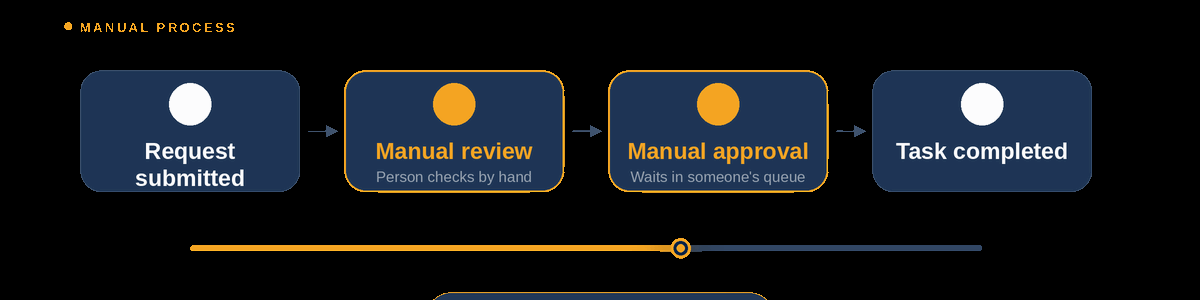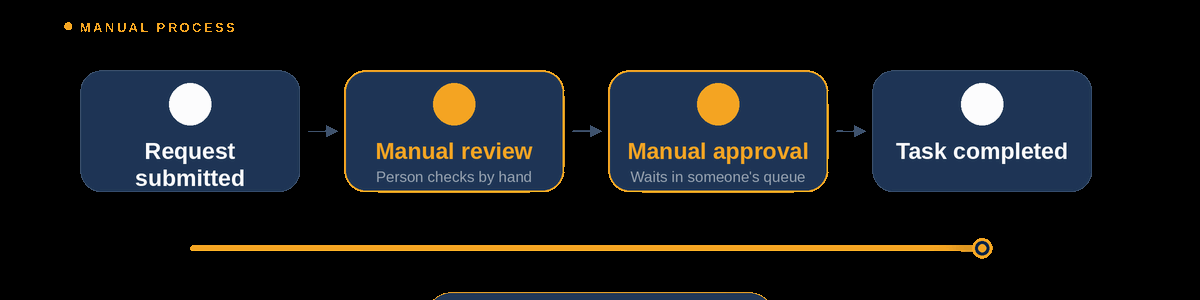
Enterprises handle enormous volumes of documents every day: invoices, contracts, onboarding forms, insurance claims, shipping documents, and regulatory filings. The vast majority are processed manually — humans reading, copying, entering, and routing data by hand. This approach is slow, error-prone, expensive, and impossible to scale. And yet, for most organisations, it remains the default.
Teams spend hours every day extracting information from documents by hand: vendor names, invoice amounts, policy numbers, customer IDs, and contract terms. Every field copied manually is a potential error, a delay, and a waste of a skilled employee’s time that could be spent on work that requires human judgment.
A single transposed digit in an invoice amount causes a payment dispute. A misread policy number delays an insurance claim. A missed clause in a contract creates a liability. Manual document processing is inherently error-prone, and in regulated industries or high-volume operations, those errors compound into significant business risk.
80% of enterprise data is unstructured — locked inside PDFs, images, scanned forms, and handwritten documents. Traditional data processing tools cannot read these formats, which means enormous amounts of valuable business intelligence is sitting inaccessible in your document archive, unavailable for analysis, audit, or automation.
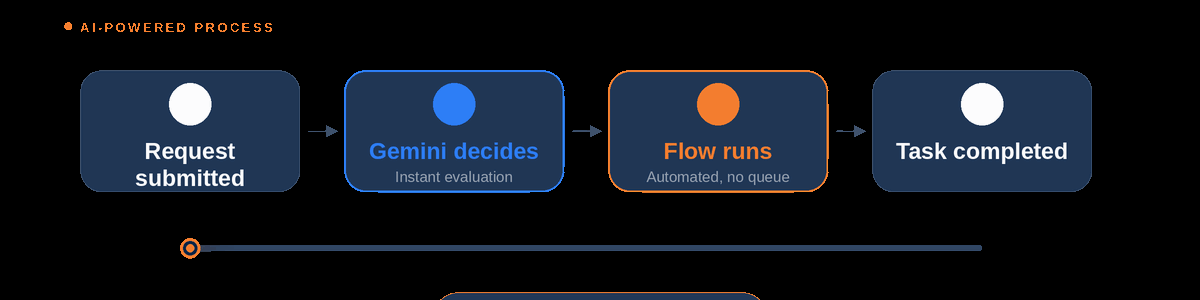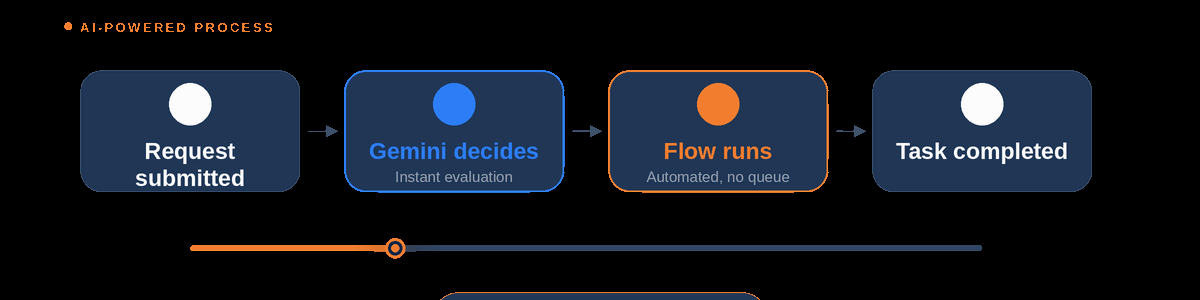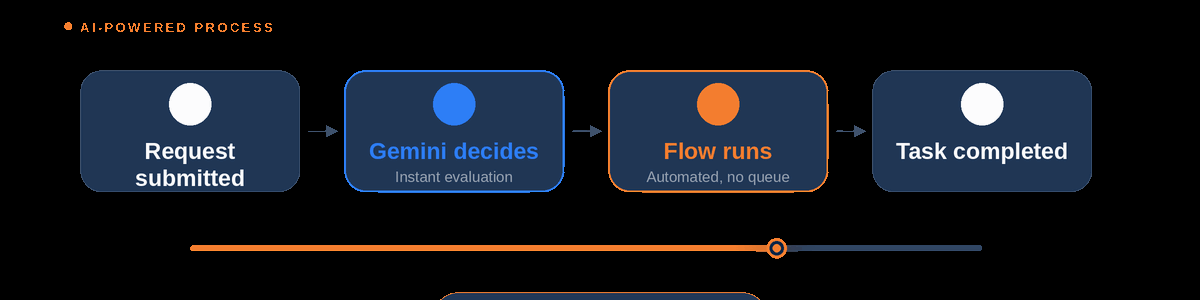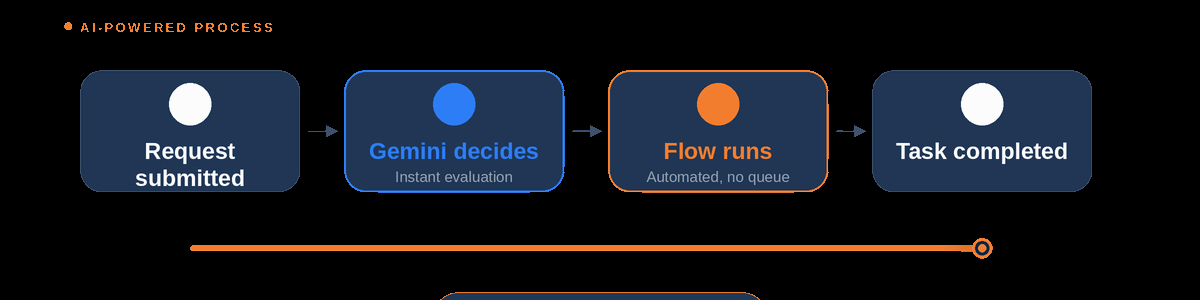
iAmaze delivers a complete Intelligent Document Processing (IDP) platform built on Google Cloud’s AI stack — combining Document AI, Cloud Vision API, and Vertex AI into an integrated solution that automates the full document lifecycle. Documents are ingested in any format, read and understood by AI, classified by type and intent, validated against business rules, and delivered as structured, actionable data to your downstream systems — automatically, at scale, in seconds.
Google Document AI processes documents with 99.5%+ extraction accuracy across standard document types, supports 200+ languages through Vision API OCR, and requires zero ML training for pre-built processors. For custom document types, Vertex AI’s GenAI-powered Custom Extractor achieves high accuracy with minimal training samples using few-shot learning.
Google Document AI is the foundation of the IDP platform. It is a machine learning-powered document understanding service that goes far beyond basic OCR — it understands document layout, relationships between elements, tables, key-value pairs, and contextual meaning.
Pre-trained processors handle the most common document types out of the box. Document AI Workbench enables custom processors for any specialised document type your organisation processes.
Document AI includes purpose-built processors for the most common enterprise document types: invoices, purchase orders, bank statements, receipts, identity documents, W-9 and W-2 forms, US driver’s licences, passports, insurance documents, and more. These processors extract the right fields automatically with no training or configuration required.
For document types not covered by pre-trained processors, Document AI’s Custom Extractor uses generative AI to extract structured data from any document — generic or domain-specific — without the need to choose a specialised processor or train from scratch. Natural language prompts describe what to extract. Accuracy improves continuously through iterative auto-labelling.
Document AI converts any unstructured document into structured, machine-readable JSON data. It understands multi-page layouts, nested tables, header and footer relationships, and document sections — not just individual field values. This structured output feeds directly into your ERP, CRM, workflow automation, or data warehouse.
For documents where AI confidence falls below your threshold, Document AI’s HITL (Human in the Loop) workflow routes to a human reviewer for validation. Reviewers see the original document alongside extracted fields, confirm or correct values, and the corrected data improves the model for future processing — continuously raising automation rates over time.
Cloud Vision API provides the image intelligence layer that handles document inputs that are not clean PDFs — photographs of documents, scanned paper forms, handwritten notes, and image-heavy files. It converts visual content into text with industry-leading accuracy across 200+ languages, handling rotation, poor lighting, and degraded image quality with advanced pre-processing.
Vision API extracts text from photographs, scanned images, screenshots, and any visual input where text is present. Whether a field agent photographs a form in the field or a customer uploads a picture of their utility bill, Vision API converts it to extractable text that Document AI can then process and structure.
Full handwriting recognition for printed and cursive text, including support for BCP-47 language codes spanning over 200 languages. Handwritten forms, notes, signatures, and annotations that would completely defeat traditional OCR are read accurately by Vision API’s specialised handwriting detection model.
The DOCUMENT_TEXT_DETECTION feature is optimised specifically for dense text documents, returning structured output that includes page, block, paragraph, word, and character bounding boxes — enabling precise field localisation and table extraction for complex, multi-column document layouts.
Process up to 2,000 images asynchronously in a single API call for high-volume batch processing, or handle up to 16 images per request for real-time applications. Vision API’s cloud architecture scales automatically to handle document processing peaks without any infrastructure management.
Vertex AI provides the customisation and advanced intelligence layer that transforms standard document extraction into a truly tailored IDP solution. When your documents do not fit standard templates, when you need AI to make decisions based on extracted data, or when you want continuous model improvement from every document processed, Vertex AI is the layer that makes it possible.
Vertex AI enables fine-tuning of document processing models with minimal training samples through few-shot learning. Where standard processors achieve insufficient accuracy on your specific document variants, Vertex AI’s GenAI-powered training improves performance with a fraction of the training data that traditional ML approaches require.
Build AI pipelines that classify incoming documents by type, intent, and processing priority before extraction begins. Mixed document batches — a combination of invoices, receipts, contracts, and correspondence arriving in a single email — are automatically identified, split, and routed to the correct Document AI processor for each type.
Every validated extraction — whether human-confirmed or AI-processed at high confidence — becomes training signal for model improvement. Vertex AI’s MLOps capabilities manage model versioning, A/B testing between model versions, and automated retraining as new document patterns emerge in your incoming data stream.
Beyond extracting what’s in the document, Vertex AI can enrich extracted data with external context — checking vendor databases, validating against contract terms, flagging anomalies, and generating recommendations. Extracted invoice data can be cross-referenced against purchase orders. Contract terms can be analysed for non-standard clauses. Vertex AI turns raw extraction into intelligent decision support.
Automate 80-95% of manual document data entry depending on document type and quality. Your team shifts from keyboard data entry to exception handling and quality oversight — a fundamentally different and more valuable use of their skills.
Google Document AI consistently achieves 99.5%+ extraction accuracy on standard document types. AI never misreads a digit due to fatigue, never copies a field to the wrong column, and applies the same rules consistently to every document every time.
Document processing cycles that took 24-72 hours through manual handling complete in seconds through IDP. Invoice approval cycles accelerate. KYC onboarding completes in minutes instead of days. Claim processing that backed up into queues is resolved on arrival.
Manual document processing requires linear headcount growth as document volume grows. IDP scales horizontally in the cloud — processing twice as many documents requires no additional staff, no additional cost per document, and no reduction in accuracy or turnaround time.
Every document processed becomes searchable, analysable structured data. Trends in invoice pricing, contract term variations, claim patterns, and onboarding completion rates become visible for the first time. IDP transforms your document archive from a static repository into a live business intelligence asset.
Every extraction, validation, and human review is logged with timestamps, confidence scores, and field-level traceability. For regulated industries — BFSI, healthcare, legal, logistics — this audit trail demonstrates compliance, supports regulatory submissions, and provides defensible evidence of process adherence.
Extract vendor details, line items, amounts, tax fields, and payment terms from any invoice format — PDF, scanned paper, photographed receipt, or emailed document. Match against purchase orders automatically. Route exceptions for human review. Update financial systems with zero manual data entry. AP teams processing hundreds of invoices daily see immediate, dramatic ROI.
Extract and validate data from identity documents — passports, Aadhaar cards, PAN cards, driving licences — automatically. Vision API reads both printed and handwritten fields. Document AI validates extracted data against expected formats. Vertex AI checks for document authenticity signals. KYC that took days of manual processing completes in minutes.
Extract parties, dates, terms, clauses, obligations, and key defined terms from contracts. Classify contract types, flag non-standard clauses, and identify missing standard provisions. Vertex AI can be trained on your organisation’s specific contract vocabulary and risk criteria, delivering AI-assisted contract review that supports your legal team rather than replacing their judgment.
Extract policy numbers, claimant details, incident descriptions, and supporting document data from claim submissions. Classify claim type and initial priority. Route to the correct handler automatically. Flag potential anomalies for fraud review. Reduce claims processing from days to hours, improve customer experience, and reduce the cost per claim substantially.
Process bills of lading, customs declarations, delivery notes, and freight invoices automatically. Extract shipment details, consignee information, commodity descriptions, and tariff codes. Validate against shipping orders and notify operations systems automatically. Reduce port delays, customs clearance time, and the risk of documentation errors that cause shipment holds.
Automate the intake and processing of CVs, offer letters, joining forms, tax documents, and benefits enrolment forms. Extract structured data from any form format, validate completeness, route for approval, and update HR systems automatically. New employee onboarding that generates hours of HR data entry work is completed in minutes with IDP.
Implementing IDP effectively requires expertise across multiple technical domains: Google Cloud AI configuration, OCR pipeline design, ML model training, enterprise system integration, and change management for teams transitioning from manual to automated document workflows. iAmaze brings all of these capabilities in a single, certified team.
iAmaze holds Google Cloud certifications with proven expertise in Document AI, Cloud Vision API, and Vertex AI. We have designed and deployed IDP solutions across BFSI, healthcare, logistics, legal, and manufacturing sectors — with deep knowledge of the real-world complexity that enterprise document processing demands.
Not every organisation processes the same documents. We assess your specific document types, quality characteristics, and volume patterns before designing your IDP architecture. Pre-trained processors where they fit. Custom extractors where standard models fall short. Vertex AI enrichment where the business logic demands it.
We do not stop at document extraction. We integrate the structured output from your IDP pipeline into your downstream systems — ERP, CRM, workflow automation, data warehouses, and compliance platforms. Your documents feed your systems automatically, without any manual handoff required.
Low-confidence extractions should not fail silently or auto-approve incorrectly. We design human review workflows that route exceptions intelligently, present reviewers with clear context, capture corrections to improve model performance, and maintain complete audit trails for regulatory compliance.
We establish baseline metrics before deployment: current processing time per document, error rates, headcount dedicated to manual processing, and cost per document. Post-deployment, we measure and report the same metrics, so the business case for IDP is continuously validated with real data.
Document formats evolve. New vendors introduce new invoice layouts. Regulatory changes add new fields to compliance documents. iAmaze provides model maintenance and improvement services — ensuring your IDP accuracy improves over time rather than degrading as your document landscape changes.
Our IDP delivery framework moves from understanding your document landscape to live, production-quality automation in a structured, low-risk sequence.
We audit your current document workflows, identify the highest-ROI automation opportunities, and map the data fields requiring extraction for each document type.
We design the Document AI processor configuration, Vision API OCR pipeline, and Vertex AI classification and enrichment model architecture for your specific document portfolio.
We build and configure the full IDP stack, integrate with your ERP, CRM, or workflow systems, and configure human-in-the-loop validation for low-confidence extractions.
Full testing against your document samples, monitored production deployment, team training, and ongoing model improvement as your document types evolve.
The platform processes any document format your organisation receives. Google Document AI handles PDFs, TIFF, JPEG, PNG, BMP, GIF, and WebP formats. Cloud Vision API processes photographs and images taken in any condition. Together, the platform handles printed documents, scanned paper, photographed forms, email attachments, and handwritten notes across all common file formats.
Document AI achieves 99.5%+ accuracy on standard document types with pre-trained processors. For custom document types or poor-quality scans, accuracy varies. Our IDP architecture always includes confidence thresholds: extractions above the threshold proceed automatically. Extractions below the threshold route to a human reviewer through the Human-in-the-Loop workflow, who validates and corrects values. Every human correction improves the model for future documents.
Pre-trained processors for common document types require no training at all. They work accurately from day one on standard invoices, identity documents, bank statements, and more. For custom document types unique to your organisation, Document AI Workbench and Vertex AI use generative AI-powered few-shot learning to achieve high accuracy with minimal training samples. Most custom models reach production accuracy within days, not months.
Document AI outputs structured JSON data that integrates with any system via API. iAmaze builds the integration layer that connects your IDP pipeline to your ERP, CRM, workflow automation tool, or data warehouse. We have implemented IDP integrations with SAP, Oracle, Microsoft Dynamics, Salesforce, ServiceNow, and custom-built systems. If your system has an API or can receive structured data, we can connect it.
A focused pilot IDP implementation — such as invoice processing or KYC document extraction — typically goes from kick-off to live in six to eight weeks. Cost depends on document volume, number of document types, integration complexity, and whether custom model training is required. iAmaze provides a detailed ROI analysis and implementation estimate after a one-hour discovery call.
Our first consultation is free, takes 45 minutes, and comes with no obligation and no pitch. We review your current technology landscape, identify the top three opportunities by business impact, and tell you honestly whether iAmaze is the right fit. If we are not, we will tell you that too.
Monday to Friday, 10:00 AM – 6:00 PM
At iAmaze we provide the best consultancy services for your business.